
LLM apps in Rust
What you end up with: a service that answers questions about your own documents — chunks and embeds them, searches by vector similarity, and streams an answer, with the inference running either locally or against a hosted API.
Most AI app tutorials assume Python. Rust is not a worse choice: it is how you ship an AI feature that has to be fast, memory-hungry in the right places, and deployable as a single binary. This track is written for backend developers, not researchers.
What you’ll build
Section titled “What you’ll build”- A document pipeline: chunking, metadata and an embedding store
- Vector similarity search, first brute force, then an index
- Streaming responses over HTTP with Server-Sent Events
- Local inference with
candle, and switching to a hosted API without rewriting the app - Prompt templates and token counting
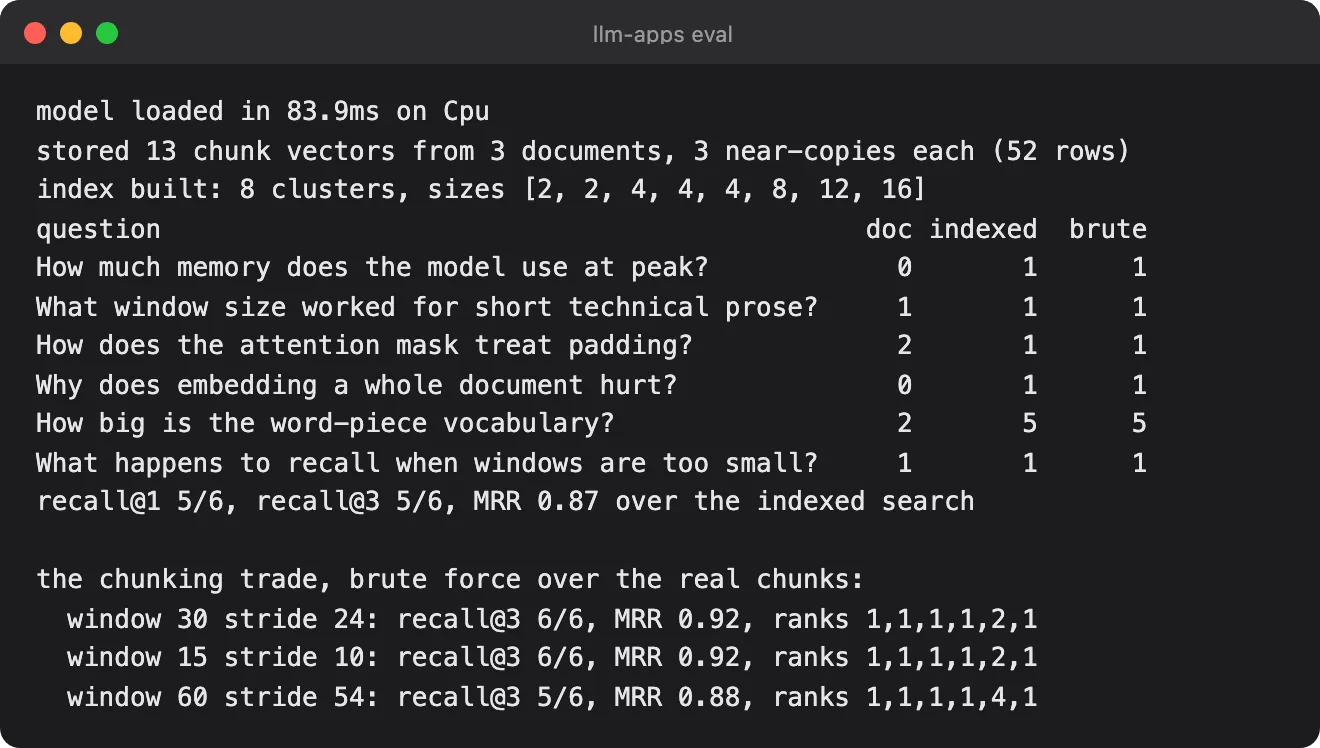
- Evaluation: does the retrieval actually find the right chunk?
- Cost and latency budgets you can defend
Articles
Section titled “Articles”- What we’re building: a local RAG serviceretrieve, then answer, no cloud
- Running a model locallythe runtime, the weights, and the memory it needs
- Embeddings and vector similaritycosine distance on real vectors
- Chunking documents for retrievalsize, overlap, and what you lose
- A vector store in SQLitebrute force first, then an index
- Retrieving and promptingbuilding the context window, and the prompt
- An HTTP API for questionsstreaming answers to a client
- Evaluating retrieval qualitya small labelled set, and honest numbers
Before you start
Section titled “Before you start”Concurrency and async and Practical crates — this track is mostly async plumbing around a model call.